On 21 September 2026, SpaceXAI published Introducing Grok 4.7 and posted on X:
Grok 4.7 is here.
It’s a notable improvement over Grok 4.6 at the same price and speed.
A follow-up in the same thread said it is available now in Cursor, Grok Build, and the Grok API, with the launch post at x.ai/news/grok-4-7.
What was announced
From the official launch post and Grok 4.7 docs:
- Grok 4.7 is described as SpaceXAI’s most capable model for coding and knowledge work.
- It uses a new, larger base model than Grok 4.6 and a longer reinforcement-learning run weighted toward tasks that take many hours.
- The company says it is better at verifying its own work and managing longer context, and that it was trained to natively understand the Grok Bot harness.
- Served at the same starting price and speed as Grok 4.6.
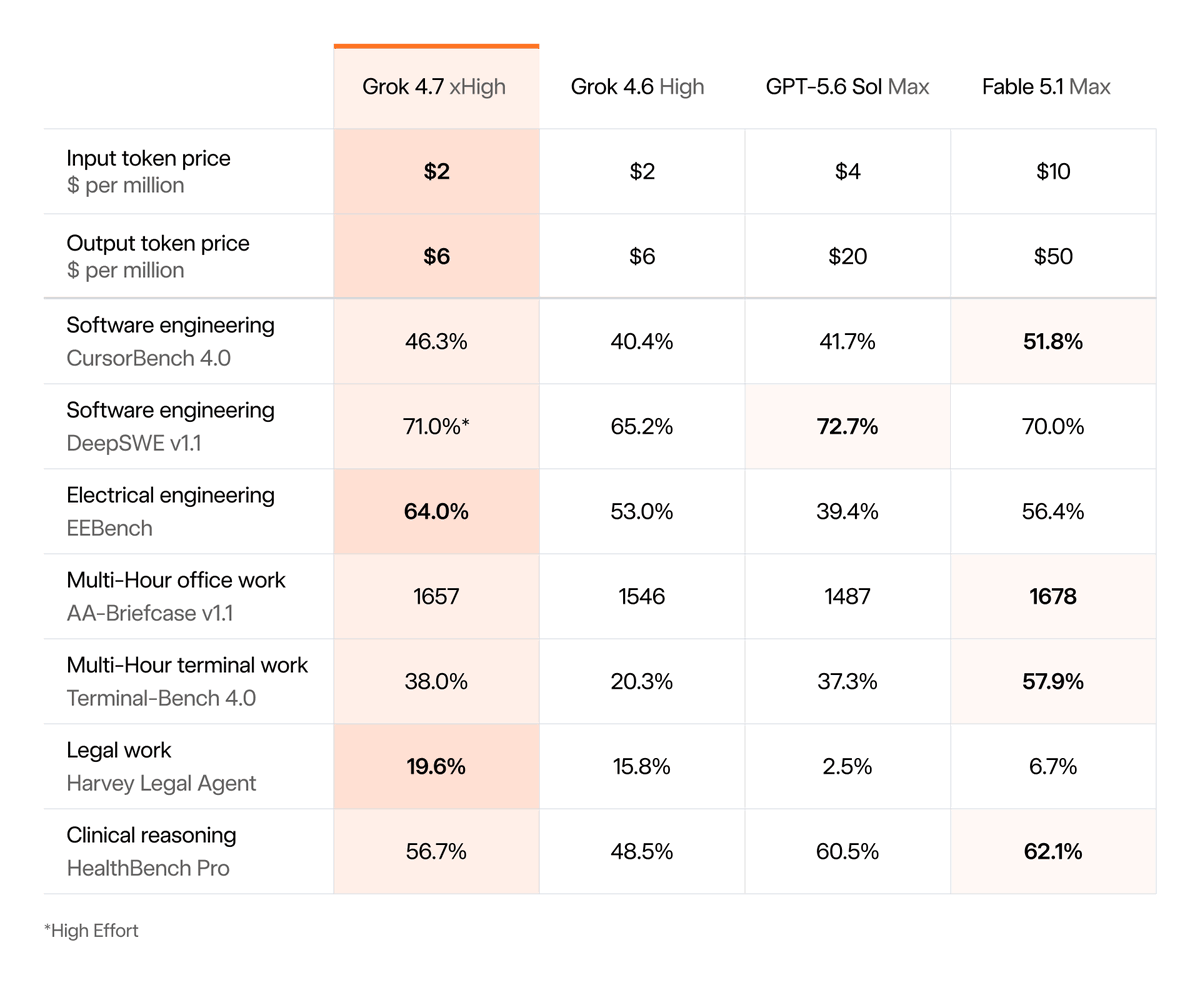
- Starting price: $2 per million input tokens and $6 per million output tokens. Docs list cached input at $0.50 / 1M below 200k prompt tokens, and $4 / $1 / $12 above that threshold.
- Context window: 500,000 tokens. Knowledge cutoff: May 2026. Text and image input; text output. Model name:
grok-4.7. - Reasoning effort: low, medium, high (default), or xhigh.
- A fast variant (twice the output speed at twice the token rates) is available in Cursor and Grok Build only, not on the public xAI API.
- Also available through third-party coding harnesses, model routers, and cloud platforms.
Benchmarks published by SpaceXAI
Figures below are from the launch table (Grok 4.7 xHigh vs Grok 4.6 High vs GPT-5.6 Sol Max vs Fable 5.1 Max). They are the company’s published scores, not an independent re-run.
- CursorBench 4.0: 46.3% (4.6: 40.4%; GPT-5.6 Sol: 41.7%; Fable 5.1: 51.8%)
- DeepSWE v1.1: 71.0%* high effort (4.6: 65.2%; GPT-5.6 Sol: 72.7%; Fable 5.1: 70.0%)
- EEBench: 64.0% (4.6: 53.0%; GPT-5.6 Sol: 39.4%; Fable 5.1: 56.4%)
- AA Briefcase v1.1: 1,657 (4.6: 1,546; GPT-5.6 Sol: 1,487; Fable 5.1: 1,678)
- Terminal-Bench 4.0: 38.0% (4.6: 20.3%; GPT-5.6 Sol: 37.3%; Fable 5.1: 57.9%)
- Harvey Legal Agent Benchmark: 19.6% (4.6: 15.8%; GPT-5.6 Sol: 2.5%; Fable 5.1: 6.7%)
- HealthBench Professional: 56.7% (4.6: 48.5%; GPT-5.6 Sol: 60.5%; Fable 5.1: 62.1%)
The launch post also says Grok 4.7 improves on Grok 4.6 on GDPval and AA Briefcase for professional knowledge work.
Safety notes in the launch post
SpaceXAI says Grok 4.7 uses a new safeguard stack. On LatchBio’s biosafety benchmark it reports 62.4%. On HackerBench v0.3 it reports allowing 3.3% of risky dual-use prompts through. Select cybersecurity partners have invite-only access to red-team capabilities for defense research.
Context
This is a model release, not a consumer-app-only update. @grok later said the model is live on API, Cursor, and Build, and heading to the consumer app soon. An earlier Grokati brief covered the 2 September “about 10 days” timeline; that was a forecast, not this ship date.
Limits of this report
Parameter count is not stated in the launch post or the Grok 4.7 docs page used here. Independent harness scores (for example Artificial Analysis) can differ from SpaceXAI’s published table; those third-party figures are not restated in this brief. Plan gating inside Cursor or Grok Build beyond the Fast-variant note is not specified in the sources above.
Source
Introducing Grok 4.7, 21 September 2026.
Grok 4.7 docs and release notes, 21 September 2026.
@SpaceXAI on X, 21 September 2026.